How we ran Terminal Bench 4.0 15% cheaper and 10% faster than the frontier labs
Benchmarking Omnara with Terminal Bench 4.0
On this page
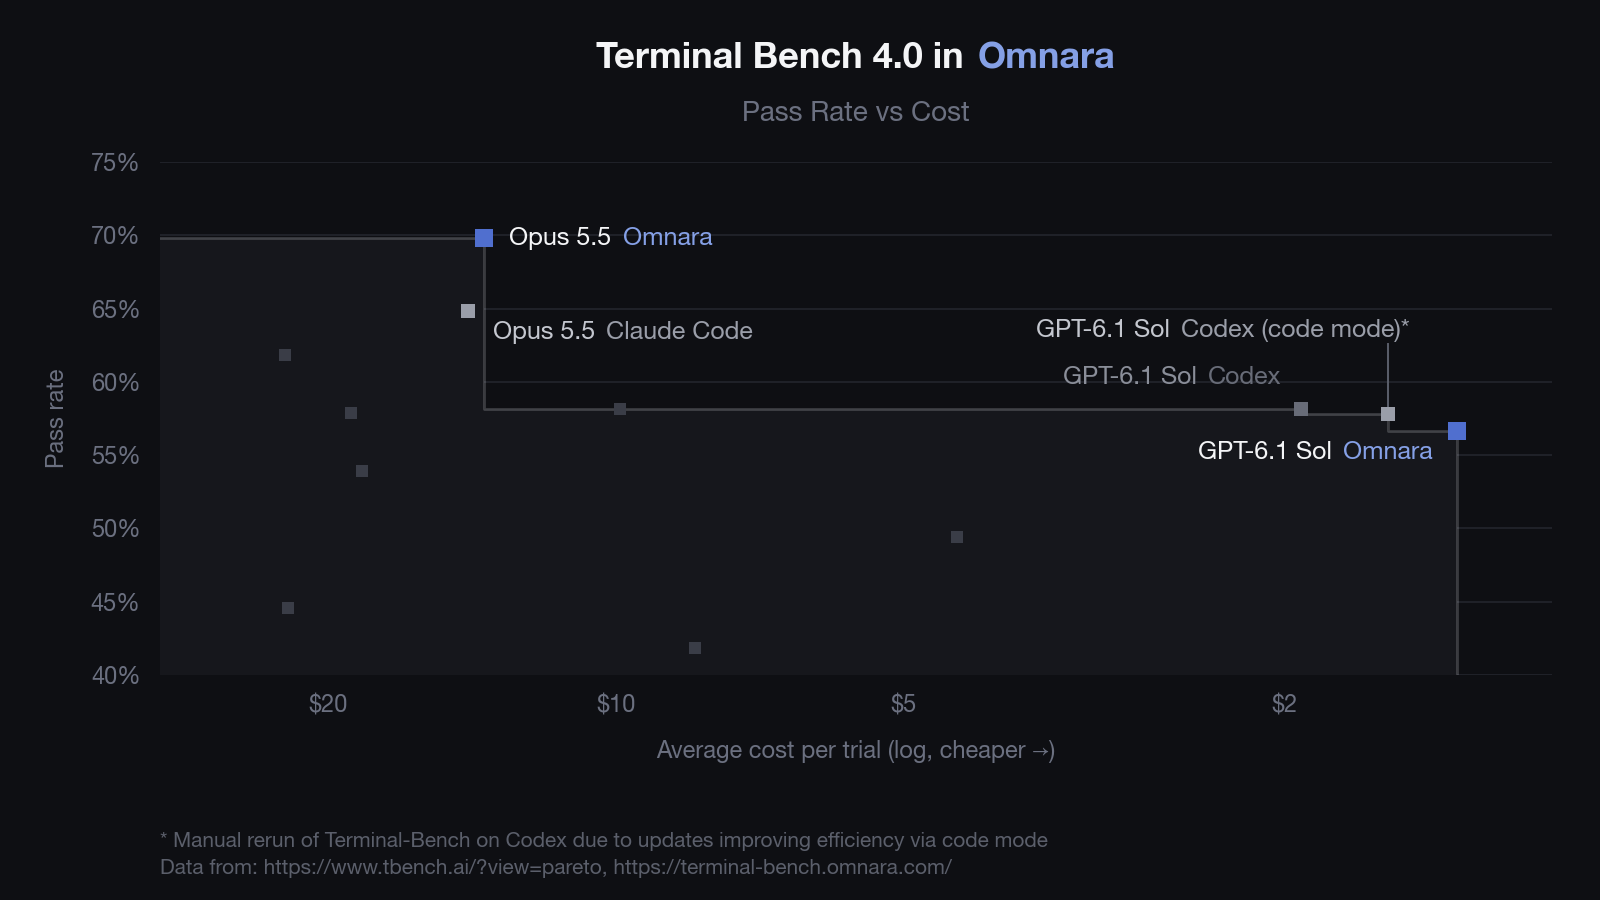
Building a reliable, performant harness is difficult, so difficult that some say only the labs can do it well. Fortunately, this isn’t true: on Terminal Bench 4.0 our Omnara harness matched the pass rates of Claude Code and Codex while costing less and for some harnesses completing faster!
Omnara is an open-source, model-agnostic platform built for deploying and running agents. Rather than running locally inside an environment, our agent loop functions directly on our cloud and interfaces with a target machine.
To achieve these cost and time savings, we’ve tuned our open-source harness and tool architecture for token efficiency, without sacrificing on performance. We’ve made our results fully accessible and want to show how we achieved this with our improved tool sets.
Running the benchmark
Omnara works with any model, so we decided to test it against the labs’ harnesses. We ran Terminal-Bench 4.0 with two frontier models, Claude Opus 5.5 and GPT 6.1 Sol, both at max reasoning effort. We compared the results against its lab’s own harness: Claude Code for Opus and Codex for Sol.
Claude Code and Codex are CLIs that run inside the task’s sandbox. Omnara’s agent loop runs on our cloud instead, and reaches a machine through omnarad, a small daemon. For each task, Harbor, Terminal-Bench’s task runner:
- Starts a Modal sandbox, which has installed
omnaradin it1 - Launches an Omnara agent with that sandbox attached as its machine
- Evaluates the results in the sandbox once the Omnara agent has completed its turn2
Attaching a sandbox to an agent config gives the agent Omnara’s standard machine toolset, described in the tool architecture section below.3 Omnara is a general agent, so it doesn’t come with a default system prompt. Instead, we adapted the Claude Code and Codex system prompts to Omnara’s featureset for use in our Omnara Opus and GPT agent’s config respectively. Both models ran at max reasoning effort with a 128k output cap, matching their native harnesses. Web search and fetch were turned off, as the leaderboard rules require.
Cost comparisons
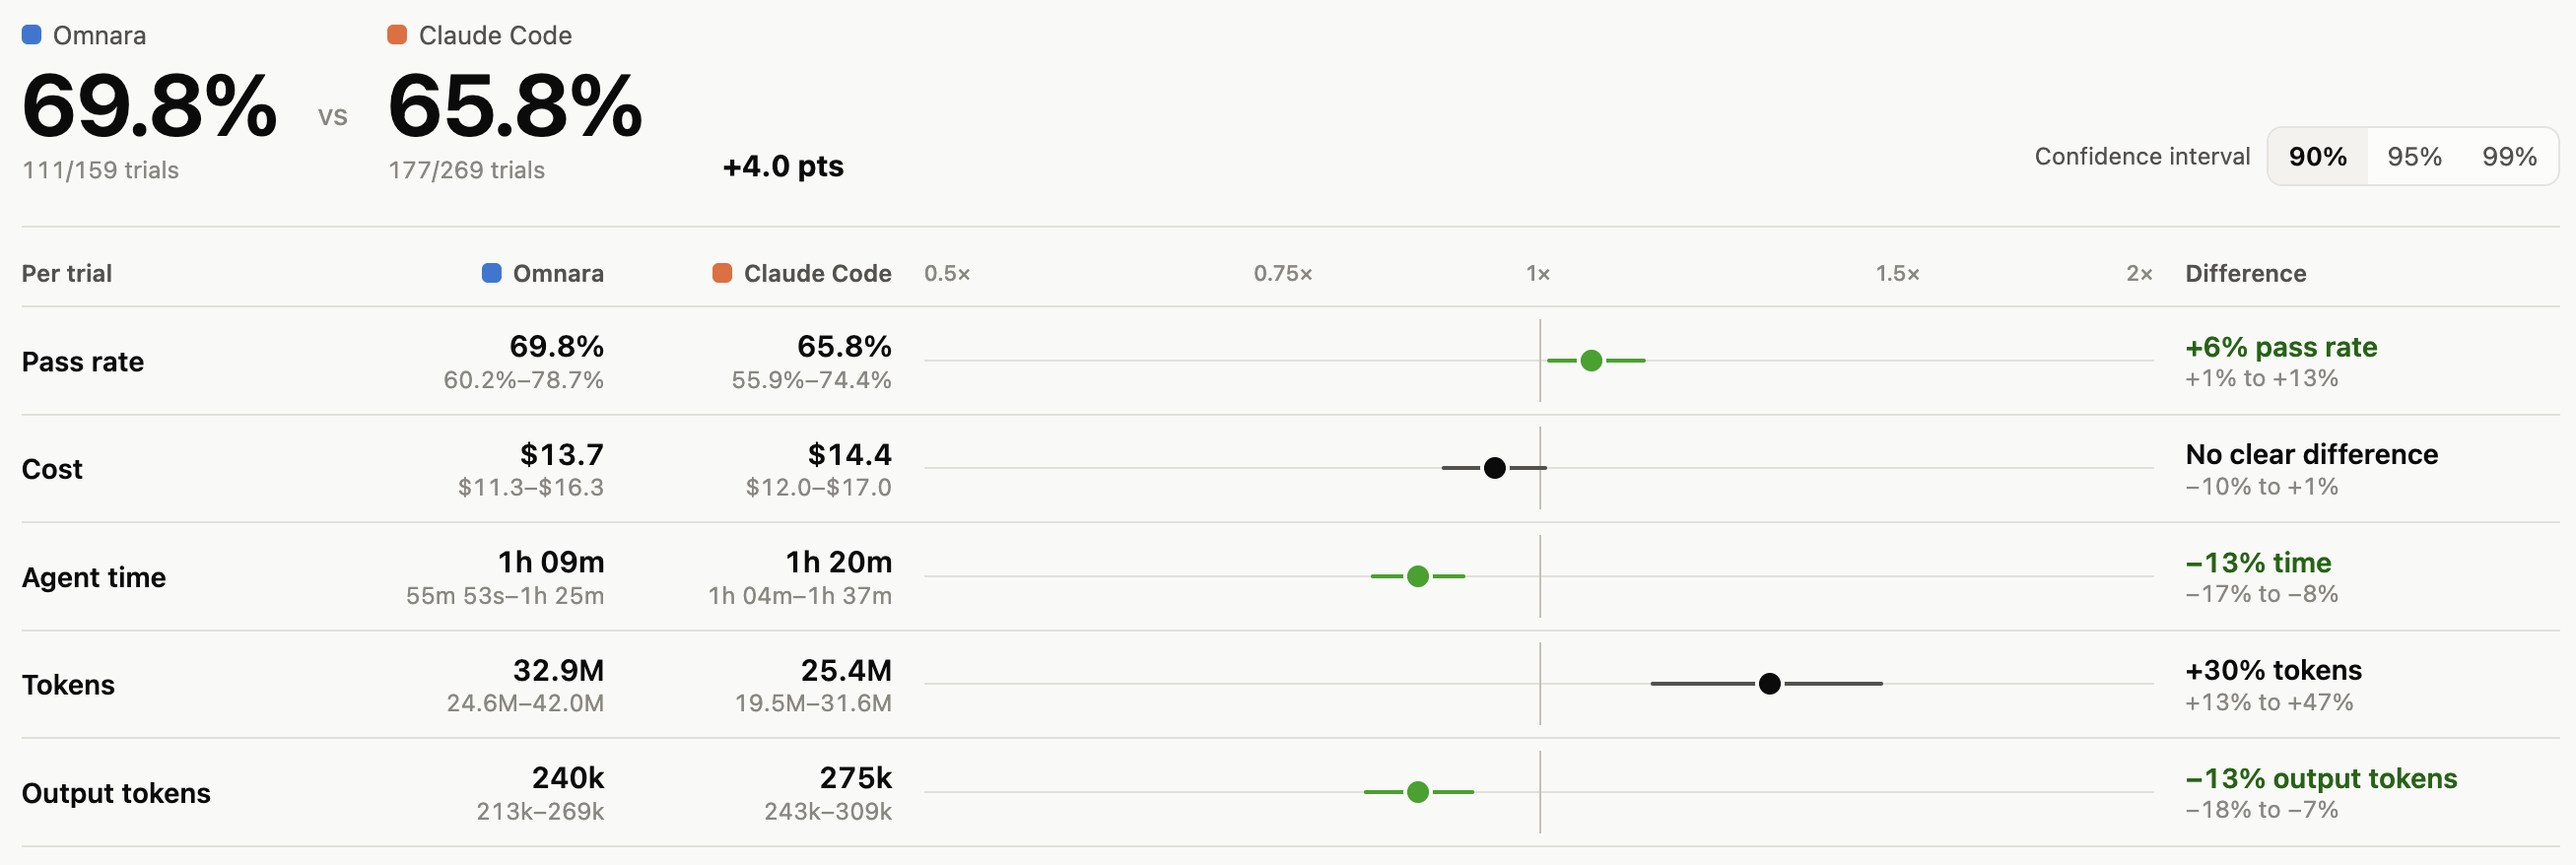
In the Omnara harness, Claude Opus 5.5 (max) performs 4 points better on average than in Claude Code. It gives that performance faster, at a marginally lower cost. It cost around 5% less and takes 13% less time to complete its tasks. In certain extreme cases, like in the task embedding-drift-monitor, both Omnara and Claude solve the task consistently, but Omnara is significantly more efficient. For Claude, it’s a nearly 1 hour task costing $8.54 on average, but for Omnara, it’s a task that spends half the time and half the money.
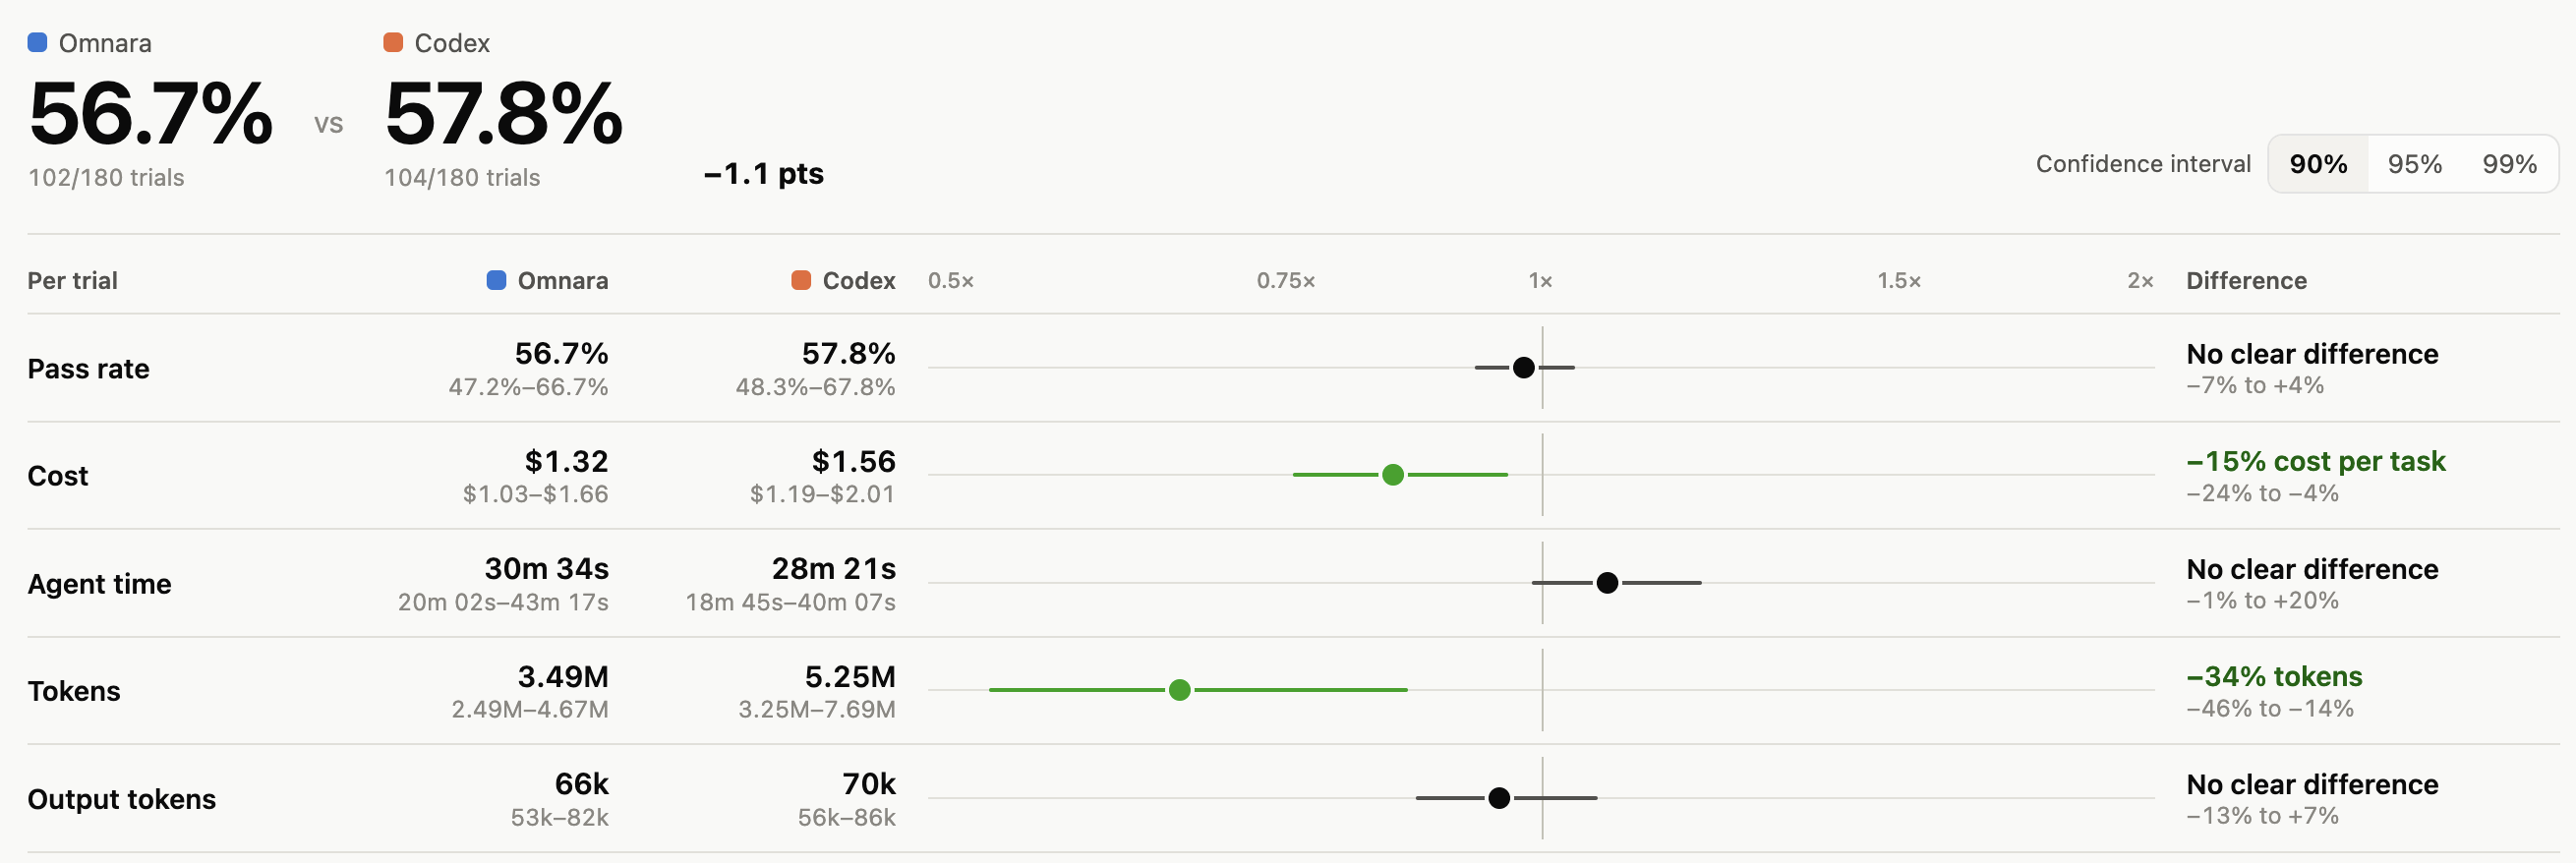
With GPT 6.1 Sol, the Omnara harness performs within the margin of error of the Codex harness.4 But, it has an even wider efficiency gulf to Codex. The cost per task of the Omnara harness ends up 15% less than in Codex, with 34% fewer tokens. In nextjs-performance, both Omnara and Codex solve the task consistently, but Omnara is again more efficient. For Codex, it’s a 30 minute task costing $1.81 on average, but for Omnara, it takes 20 minutes and costs $1.18, about a third less time and money.
Why is Omnara Cheaper?
If the labs have so much effort invested in their harnesses, how is our harness able to perform more efficiently? The trick that Omnara uses is that it defers most context, especially when executing processes.
Omnara exposes a slightly different toolset from most other harnesses. Rather than a single blocking exec / run_command tool, Omnara exposes a run_command tool, which does not block the agent loop for long commands, and instead returns a process_id, which the agent can pass into other process management tools. Then, the agent can use tools like read_process, write_process and watch_process to interface with the process later.5
This tool architecture results in a few benefits:
- Waiting without polling: Most terminal bench tasks take nearly an hour, and some even last up to 8 hours. Most of that time, the model is waiting for results. Codex commonly sleeps to wait for results. Omnara implements process exit notifications and watch_process functionality, which automatically reinvokes the model after some task completes. This reduces latent token usage and the number of tool calls substantially.
- Most exec output is deferred: Tool results carry at most 16k, which is about half of Claude. This results in substantially lower input tokens. These outputs can always be searched through or fetched later, which is almost always faster than loading all of that extra context into the input tokens and taking time to reason based on that.
As a result, Omnara produces more efficient tool calls than Codex and Claude. The agent no longer has to poll substantially for longer work, and more context is omitted by default. These benefits result in 15% cost savings versus Codex, around 5% versus Claude Code, and 13% faster task completion versus Claude Code.
Polling is one of the clearest differences. When Codex starts a long command, it either blocks until the command finishes or sleeps and checks back on it, and every check is another model call that resends the whole conversation. Omnara’s agent hands the process to watch_process and is woken only when there is something to read.
You can concretely see the payoff of this tool architecture in tasks both harnesses solve. In embedding-drift-monitor, Opus passes every run in both harnesses, but in Omnara it needs 44 model calls instead of 63, finishes in 30 minutes instead of 57, and costs $4.61 instead of $8.54. In nextjs-performance, Sol passes every run in both harnesses with a similar number of model calls, but Omnara’s deferred tool output cuts its tokens from 4.40M to 2.98M, so it finishes in 20 minutes instead of 30 and costs $1.18 instead of $1.81.
What’s next?
The labs build great models, and a high-performing harness paired with a reliable platform are force multipliers for those models. We at Omnara are always iterating on our tool architecture, and strive to be the best place for you to deploy your agents.
Every trace from this run is in our results viewer, and the harness code is on GitHub. If you want this efficiency for your own agents, with any model and on any machine, try Omnara today.
Footnotes
Footnotes
- We chose to use Modal for our Terminal-Bench evals, but Omnara supports 12 different sandbox providers AND bring your own machine
- We excluded security tasks, tasks the model refused, and one task whose reference solution fails from our analysis. For Opus, we omitted 12 tasks: 5 security tasks, 6 refusals, and the broken-reference task. For Sol, we omitted 6: the 5 security tasks and the broken-reference task.
- Tasks that required MCPs or skills were attached to the agent config on demand
- We ran Codex 0.166.0, a more efficient version than the one benchmarked on the tbench.ai leaderboard (submitted September 29, 2026)
- Notably, we haven’t tested a code mode implementation in our harness yet. We found that our non-code mode implementation already outperforms codex, which utilizes code mode natively. We’d likely benefit from code mode, but only marginally because our toolset provides most of the benefits of deferring and omitting large tool results from context.